Jiaojiao FanI am a Senior Research Scientist at NVIDIA Cosmos Lab in Santa Clara, California, where I work on world foundation models. Currently, I am working on improving Cosmos, NVIDIA's open-sourced groundbreaking world foundation model for Physical AI. I completed my PhD in Machine Learning at Georgia Institute of Technology in 2024, where I was advised by Prof. Yongxin Chen. During my PhD, I was fortunate to do internships at NVIDIA research, Snap Creative Vision Research, and Microsoft Research. |
|
NewsMay 2026
Cosmos 3 launched at GTC Taipei — omnimodal world models for Physical AI.
Jan 2026
InfoTok accepted as an Oral at ICLR 2026.
Jun 2025
Cosmos Predict2 release! SOTA world model for autonomous driving and robot arm manipulation.
Jan 2025
Cosmos Predict1 release! First open source large scale world model!
Nov 2024
Edify image paper was released! Photorealistic text-to-image generation with pixel-space laplacian pyramid diffusion.
Jul 2024
Graduated from Georgia Tech and joined Nvidia as a research scientist working on NVIDIA GenAI, specifically Edify text-to-image model post-training.
|
Selected PublicationsSee Google Scholar for the full list of publications → |
|
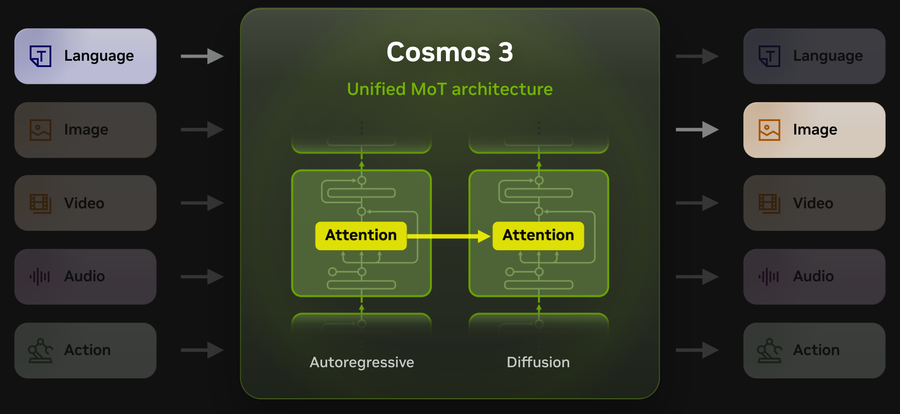
Cosmos 3: Omnimodal World Models for Physical AINVIDIA White paper, 2026 arxiv / code / website / Cosmos 3 is an omnimodal foundation model that connects understanding, generation, simulation, and action through a shared world model spanning text, images, video, audio, and actions. |
|
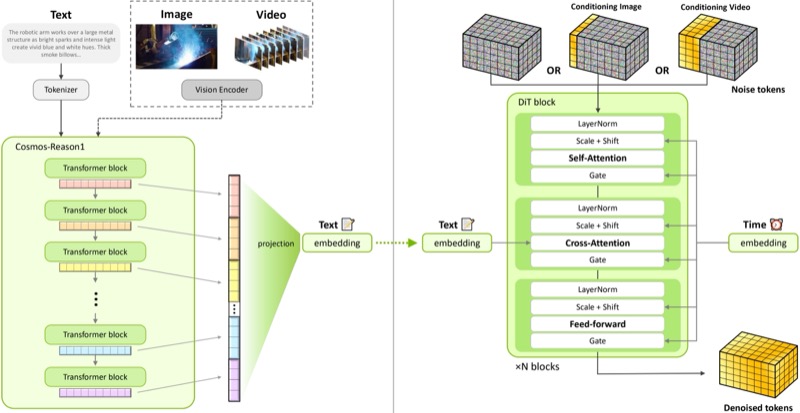
Cosmos 2.5: World Simulation with Video Foundation Models for Physical AINVIDIA White paper, 2025 arxiv / code / website / Cosmos-Predict2.5 is a flow-based world foundation model that unifies Text2World, Image2World, and Video2World generation in a single model, using Cosmos-Reason1 for improved grounding. It is trained on 200M curated video clips and refined with reinforcement learning-based post-training. |
|
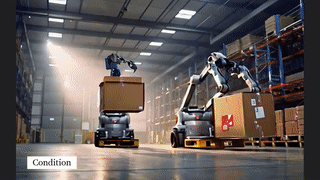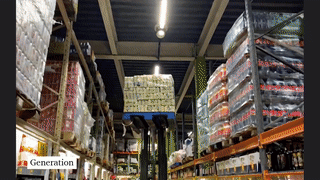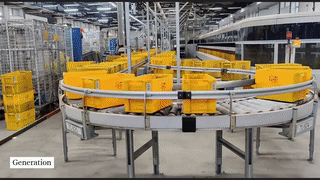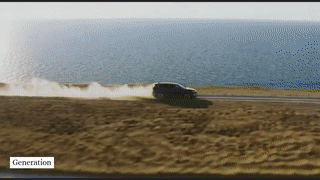
Cosmos 1: Cosmos World Foundation Model Platform for Physical AINVIDIA White paper, 2025 arxiv / code / website / Jensen Huang keynote at CES2025 / NVIDIA’s open-source video world model platform for Physical AI represents a foundational breakthrough in world modeling. Cosmos enables developers to customize, and deploy world foundation models that can understand and predict physical interactions in video sequences |
|
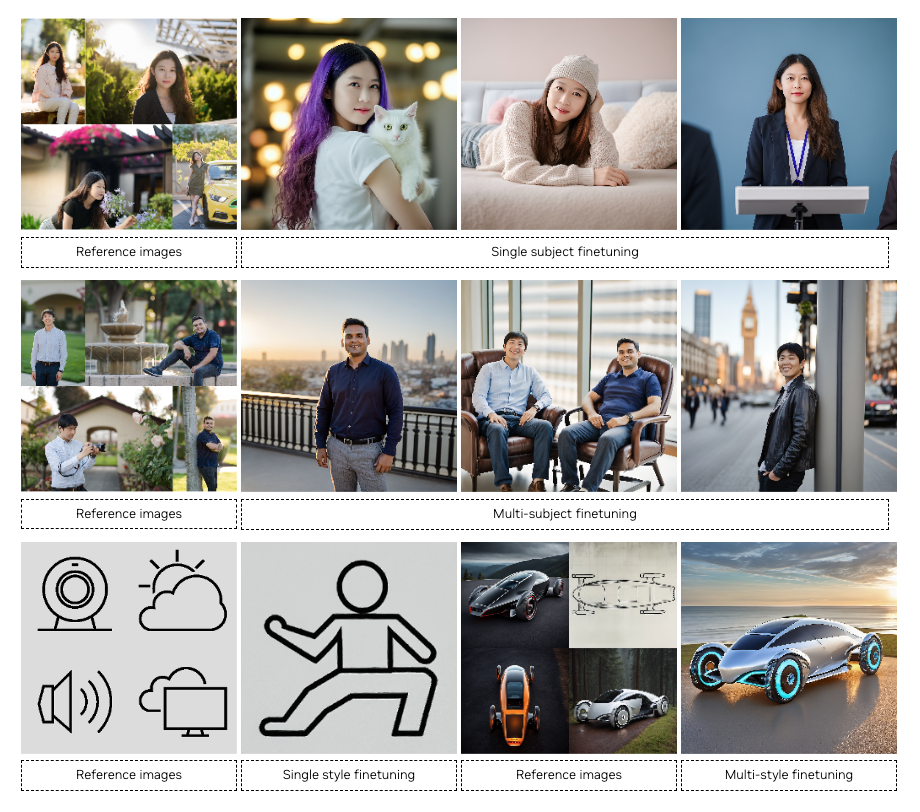
Edify Image: High-Quality Image Generation with Pixel Space Laplacian Diffusion ModelsNVIDIA White paper, 2024 arxiv / website / Edify Image is a family of cascaded pixel-space diffusion text-to-image models capable of generating photorealistic images. Edify Image delivers exceptional human personalization results with remarkable identity consistency. The model also supports style transfer, 4K upsampling, ControlNets, and 360° HDR panorama generation |
|
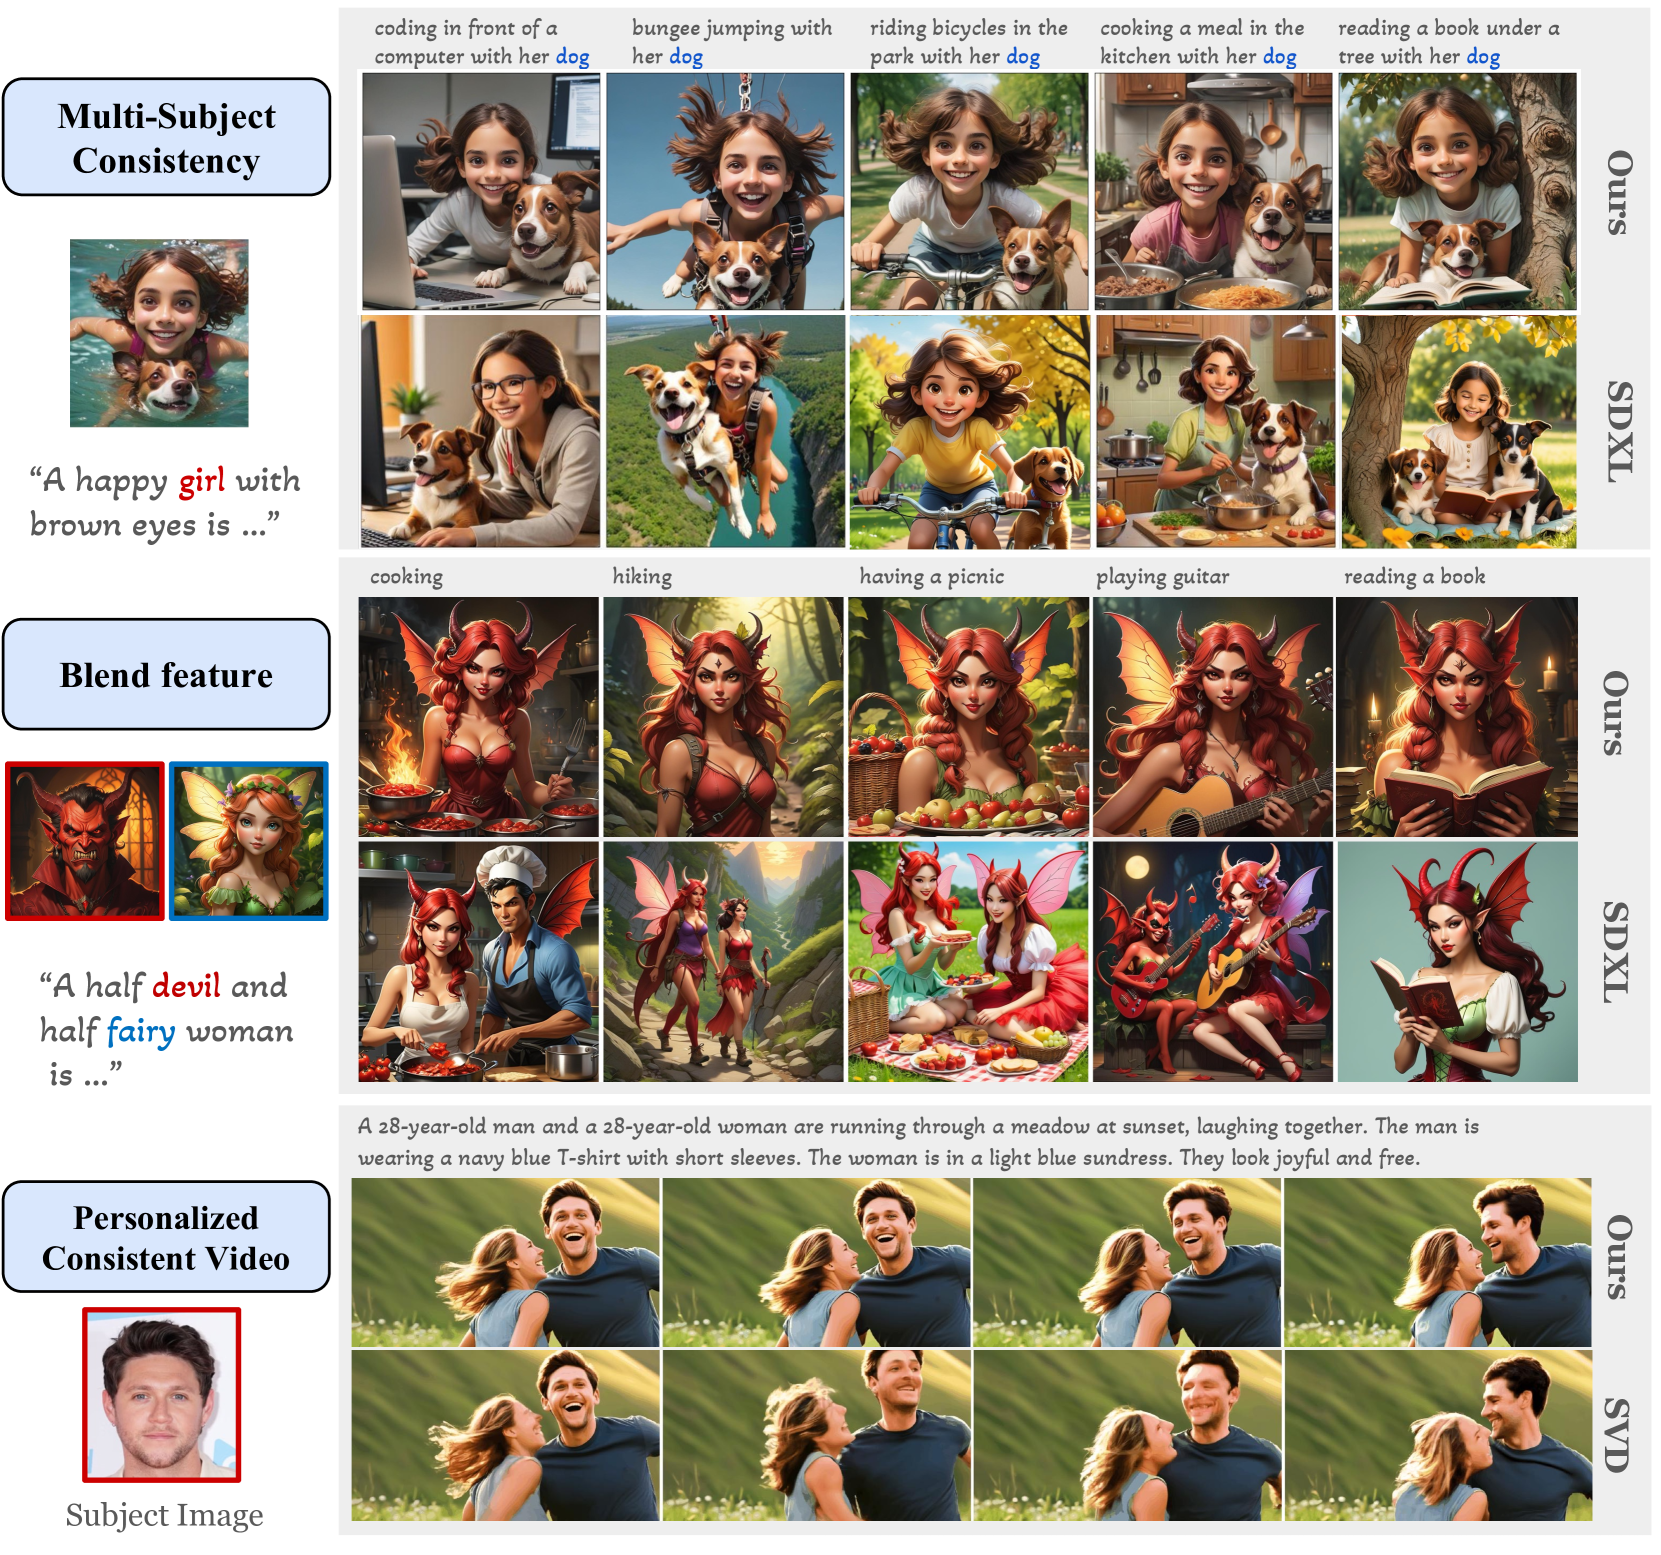
RefDrop: Controllable Consistency in Image or Video Generation via Reference Feature GuidanceJiaojiao Fan, Haotian Xue, Qinsheng Zhang, Yongxin Chen NeurIPS, 2024 arxiv / website / RefDrop is a training-free method for controlling consistency in image and video generation. By manipulating attention modules in diffusion models, RefDrop enables consistent character generation, multiple subject blending, diverse content creation, and enhanced temporal consistency in videos |
|
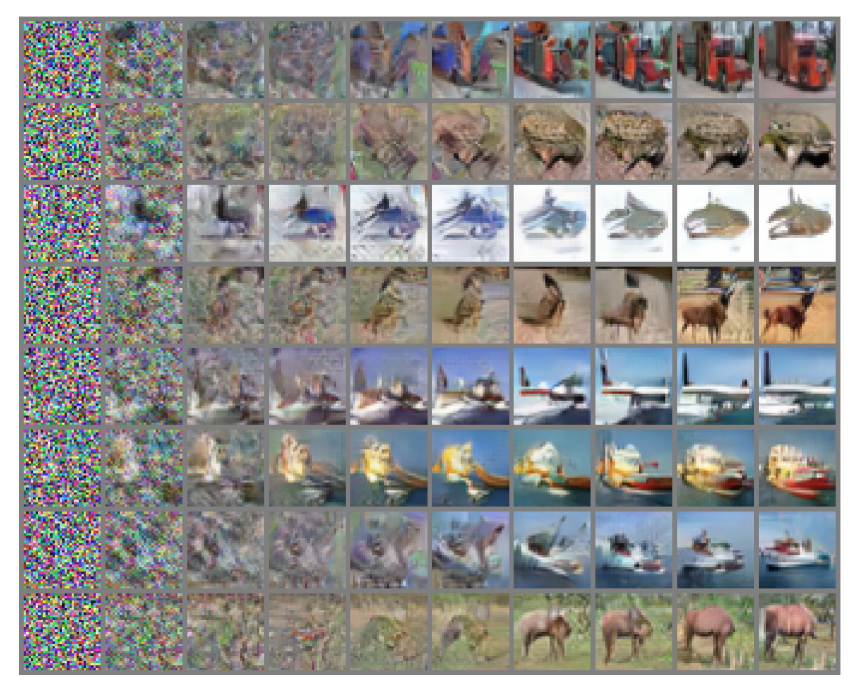
Variational Wasserstein Gradient FlowJiaojiao Fan, Qinsheng Zhang, Amirhossein Taghvaei, Yongxin Chen ICML, 2022 arxiv / code / A scalable approach to Wasserstein gradient flow using variational formulations |
|
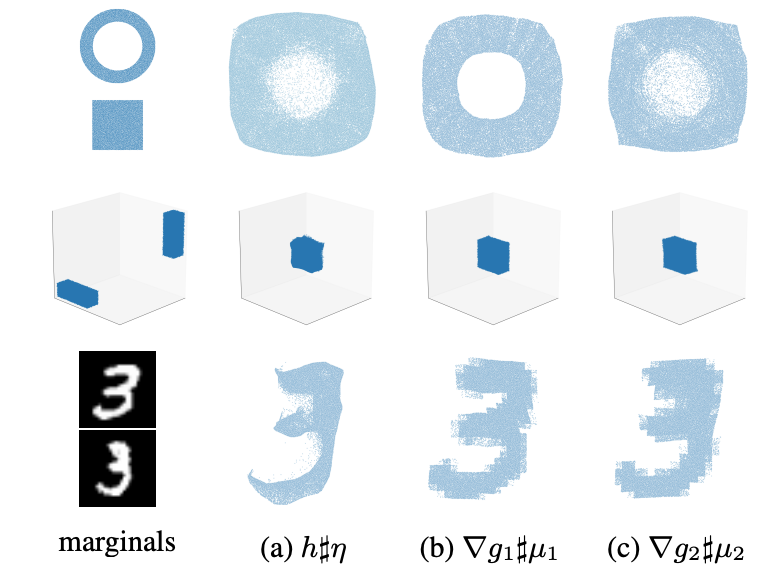
Scalable Computations of Wasserstein Barycenter via Input Convex Neural NetworksJiaojiao Fan, Amirhossein Taghvaei, Yongxin Chen ICML (long talk), 2020 arxiv / code / A novel scalable algorithm for computing Wasserstein Barycenters using Input Convex Neural Networks |
MentorshipI have had the privilege of working with or mentoring talented students and researchers. |
|
Design and source code from Leonid Keselman's website |